Published method.
Four claims. Each with its evidence.
The construct, the model, the correction and the gate. Each with the runs behind it, and a gate that can fail.
The construct.
The ruler measures how complex a line of reasoning is. Its levels come from a theory called the Model of Hierarchical Complexity. Each level builds on the one below.
- Level 7
- Level 8
- Level 9
- Level 10
- Level 11
- Level 12
- Level 13
- Level 14
A level name is a label, not a score. The published board is regenerated after the next judge runs. The bottom of the range is not mapped yet.
The measurement model.
We use Rasch measurement, in the form that lets an answer earn part credit. It puts each question and each performer on one shared scale. The scale's unit is the logit.
On that scale, a gap of one unit means the same thing at every point. A raw score cannot promise that, because a count moves when the question mix moves.
“Raw benchmark scores do not have this property.”
NIST AI 800-3, February 2026. Quoted verbatim.
AIM implements at measurement grade the latent-trait/GLMM approach that NIST AI 800-3 highlights as a promising foundation for AI evaluation statistics. AIM is not a NIST standard. It claims no endorsement.
The correction.
A judge can be harsh at one level and lenient at another. We estimate that pattern for each judge at each level, as its own term in the model. Then we correct for it.
The terms can be told apart from the data, and the method can be rerun from public data. We do not publish the values themselves.
This pattern is a diagnostic we surface so your team can act on it. It is not a problem we claim to eliminate.
Jev1 sign change beyond the band
openai-gpt-oss-120b1 sign change beyond the band
qwen3-235b-a22b-instruct-2507no sign change beyond the band
deepseek-v4-1-flashno sign change beyond the band
kimi-k3no sign change beyond the band
Above 0 = harsher. Below 0 = more lenient. Pattern only; the exact values stay in the dated report. Shaded band: plus or minus 2 standard errors. Solid dot: admitted at that level; hollow: not admitted. A ring marks a sign change that clears the band on both sides. Level along the bottom. Judge registry of record b5ecea0af663, credential vintages 2026-09-20 and 2026-09-23.
Which judge, and when to hand off.
Hand-off runs on the error bar, not on information gain. The next question is chosen for what it teaches. Each step says why.
In technical terms: the run stops on a standard error target. It picks each next question for the information it adds. A judge only grades inside the levels it is qualified for. The hand-off rule is in build.
In build.
The gate, and a gate that can fail.
Simulation
Set to an error bar of 0.20. Delivered at 0.21 once judge harshness is corrected at each level.
Simulation: 15,000 decisions on judge data from our own runs, seed 20260908. With harshness left in, the same run came in at 1.16. Error bars in logits.
We filed our first program on the Open Science Framework before any data came in. Its gates were set in advance. The current program has its own filing.
- OSF j95ef: the calibration-validity program, registered before data came in.
- OSF registration fh8yd (private until the deposit is public): the current program, registered on its own.
One gate failed. A 200-question wave failed the test for one shared dimension, and we reported that as a finding. A gate that can fail is the point.
Published judge ceilings sit at level 11, with a stated condition. None is in the current judge roster. Ceiling rule met
Checks of internal consistency.
These numbers check the method against itself. They are not a check against outside judgment. In our validation runs, rank agreement with the reference was 0.9998 and 0.9997 on two dimensions.
The stated error matched the error we saw in 96.2 and 94.8 percent of checks, on the same two dimensions.
Three LLM judges scored the same performers on the same trait. Only llama-anchor was admitted as a judge; the other two were not admitted. The same-trait correlations of 0.894 to 0.959 encode which item draw positions each performer reached, not agreement between judges, and they carry no validity evidence. A redesigned multifacet study of these judges is planned.
Relabeled September 2026. Cross-judge same-trait correlations for trait T1 run 0.894 to 0.959 across the three judge pairs. The values encode which item draw position each performer reached, not judge agreement, and carry no validity role. The heat map that showed these values is withdrawn from the site.
Metrological traceability.
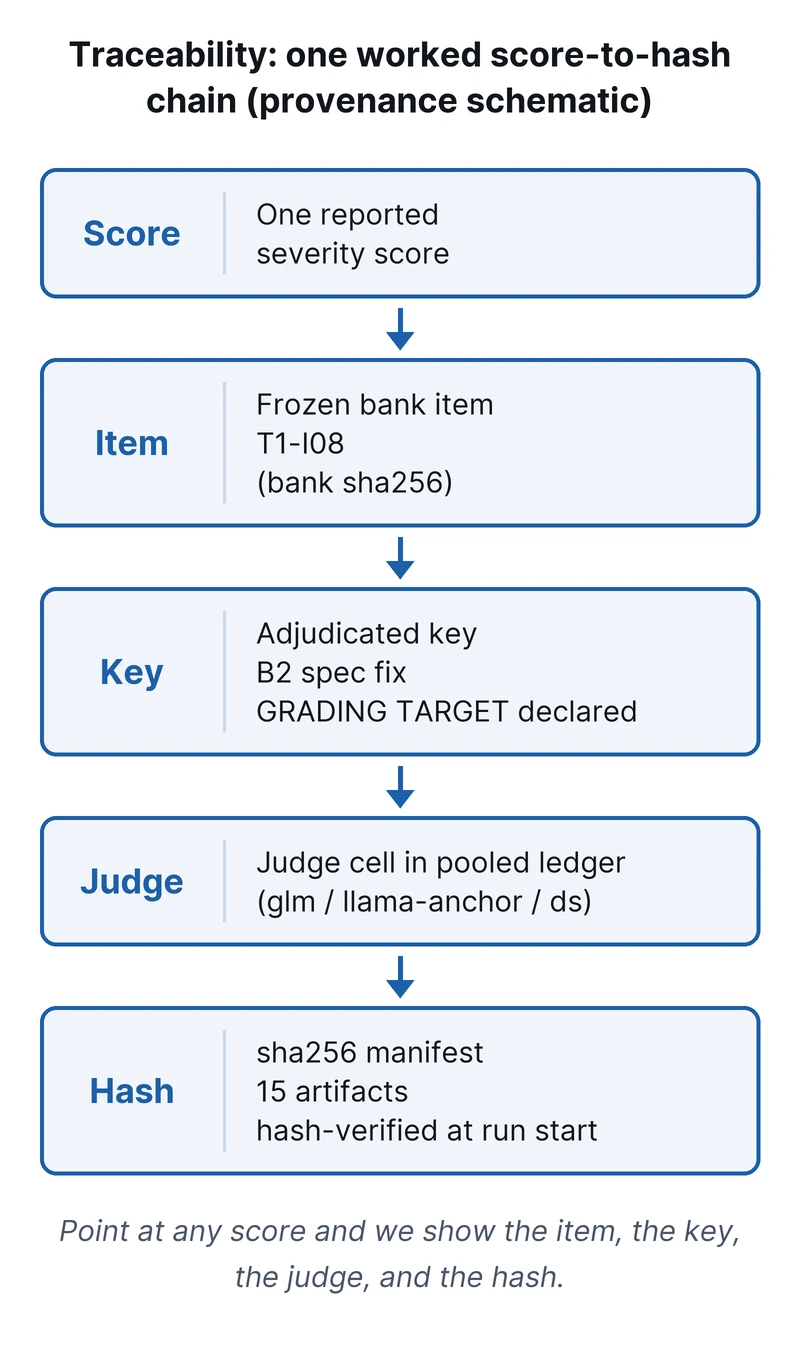
The trace chain. Each score leads back to one frozen question, with its answer key and its grading rule. Fifteen files carry sha256 fingerprints. Each run checks them before it starts.
The method is published as Chapter 3 of a book on models and metrology, edited by Fisher and Pendrill. De Gruyter published it in 2024.
How the questions are built.
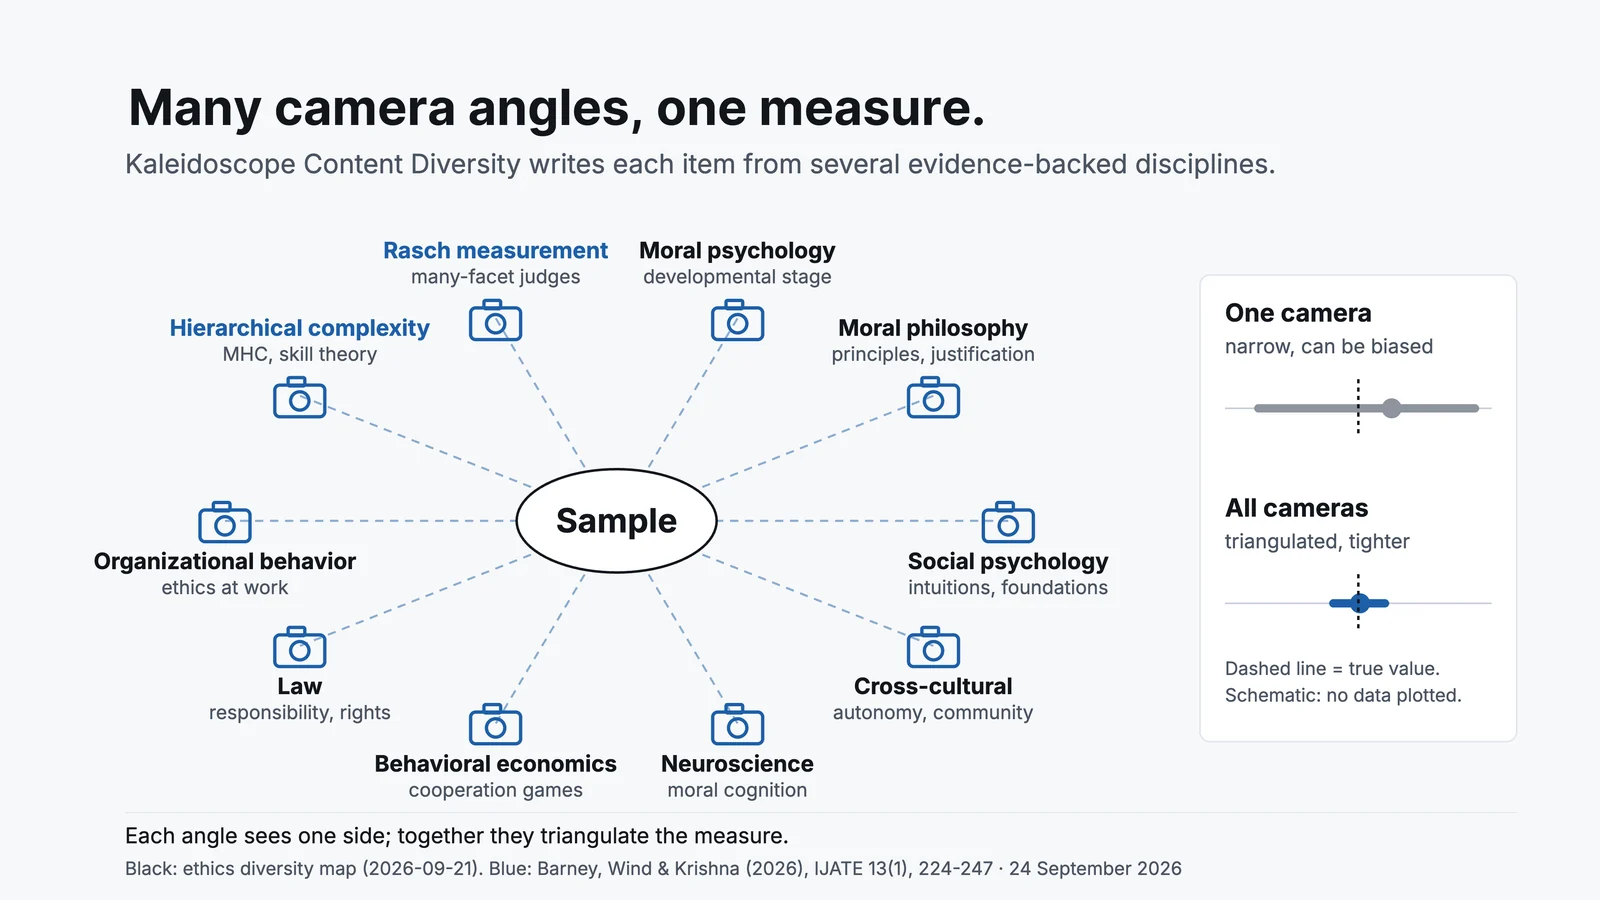
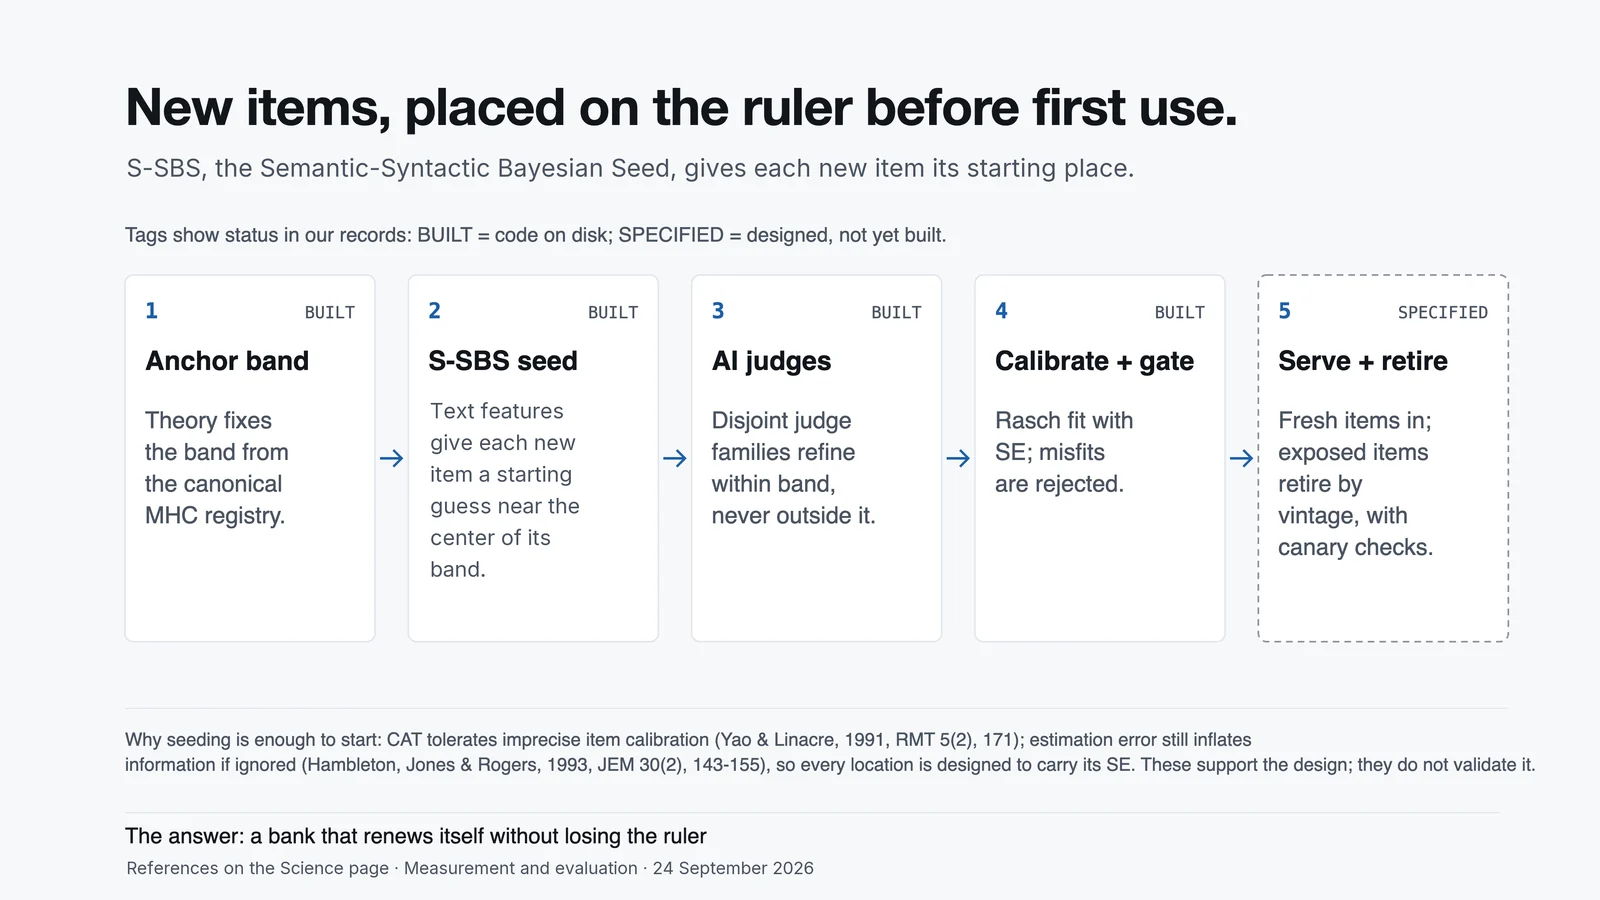
The pipeline writes many questions. It keeps the ones that fit the ruler and throws out the rest. A firewall stops any language model from setting where a question sits.
For growing traits such as hallucination, a text-based seed gives the adaptive test its starting guess. That is the seed's only job. It is not a way to place questions on its own. Proposed
Step 1. Write
The pipeline writes many questions.
Step 2. Firewall
No language model sets where a question sits.
Step 3. Keep or discard
It keeps the ones that fit the ruler. It throws out the rest.
One lane of the pipeline, as a measurement happens
The three steps above build the bank. This scene walks one lane of the instrument: an item moves from the calibrated bank, through the judge panel, onto the one ruler, and out with its uncertainty stated. The copy below makes each claim; the figure only illustrates it.
1Item enters from the calibrated bank
An item enters from the calibrated bank with its anchor location already known. The scene only shows the item taking its known place; the location comes from the bank, not from this view.
2The judge panel scores it
A calibrated many-facet panel scores the item. Judge severities are modeled and removed, not averaged away, so one harsh or lenient judge does not move the location.
3The response is located on the one ruler
The performer response is located on the one calibrated ruler. The position is an interval-scale location, so distances between performers carry meaning.
4The standard error is stated beside it
The standard error is computed and stated beside the location. Uncertainty is reported, never hidden, so the readout says how far off the position could be.
5Ships only if the uncertainty target is met
The result ships only if the uncertainty target is met. If the stated SE misses the target, the item keeps adapting rather than certifying a weak measurement.
Five states of one calibration lane. The scene illustrates the process claim stated in the copy; it introduces no number, position, or comparison the copy has not already made.
Writers and graders.
Today's questions were written by models from six companies. For the questions we are writing now, the writer, the attacker and the judges all come from different companies. And a judge never grades a question its own company wrote. See the roster.
Judges, levels 7 to 9
In the certified set. GPT-OSS 120B, Qwen3 235B and Jev hold credentials level by level (grid above); Qwen3 235B and Jev were also measured a second time. The others are still being credentialed.
- Gemma 4 31B Google
- Gemma 4 26B Google
- Gemma 3 27B Google
- GPT-6 Luna OpenAI
- GPT-OSS 120B OpenAI
- Mercury 2.5 Inception
- Mistral Small 3.2 Mistral
- Nemotron 3 Nano 30B NVIDIA
- MiMo V2.5 Xiaomi
- Qwen 3 8 Flash Alibaba level 8 only
- Qwen3 235B Alibaba level 8 only
- Jev TypeSafe

Write and attack the questions
- Writes and repairs the questions Anthropic
- Attacks the questions xAI if it passes a reliability check; Anthropic as fallback



Judges, levels 10 to 13
Candidates being screened. Not a final roster.
- A subset of the level 7 to 9 judges levels 10 to 12
- DeepSeek V4.1 Flash DeepSeek credentialed at lower levels (grid above); candidate for levels 10 to 13
- GLM 5.3 Flash Z.ai levels 10 to 12
- Kimi K3 Moonshot level 12 and up
- GPT-6 Astra OpenAI level 13, one-level trial first
Roster as of 2026-10-02. No Anthropic model judges at any level. No xAI model judges at levels 10 to 13. Flags show each vendor's home country.
Vendor and model names are used only to identify the models XLNC measures. XLNC is not affiliated with, sponsored by, or endorsed by these companies, and their inclusion does not imply their approval of any result. All names belong to their respective owners.
The ethics gate.
A gate inside the scorer sets a response to zero if it fails any of its three ethics checks. It runs before any level credit. It passed a smoke test of 7 of 7 cases, with no paid calls.
Two questions to ask any ruler.
Has the ruler moved?
The frozen reference, re-measured on two dates, each value with its error bar.
Re-measurement run: not yet published.
Is the ruler circular?
A check against outside judgment the house panel did not produce.
Validity study: not yet shown.
Honest limits.
- The measurement is gated today. Routing on it is the build, not a shipped claim.
- No judge's capability floor has been located.
- Do not write a tool call against it today.
- No simulated video is shown.
Open to reviewers. Closed to training.
The engine is open to reviewers under Apache-2.0, so reviewers can check the method. The question banks and the data that place them on the ruler stay closed. That keeps the questions out of public training data.
Glossary.
Read further.
- 2026 Barney, M., Wind, S., & Krishna, V. (2026). Using large language models to evaluate ethical persuasion text: A measurement modeling approach. IJATE, 13(1), 224-247. https://doi.org/10.21449/ijate.1788563
- 2024 Barney, M. & Barney, F. (2024). Transdisciplinary Measurement through AI: Hybrid metrology and psychometrics powered by large language models. In W.P. Fisher Jr. & L. Pendrill (Eds.), Models, Measurement, and Metrology Extending the SI: Trust and Quality Assured Knowledge Infrastructures (pp. 103-132). De Gruyter. https://doi.org/10.1515/9783111036496-003
- 2019 Barney, M.F. (2019). The Reciprocal Roles of Artificial Intelligence and Industrial-Organizational Psychology. In R.N. Landers (Ed.), Cambridge Handbook of Technology and Employee Behavior (pp. 38-56). Cambridge UP. https://doi.org/10.1017/9781108649636.004
- 2017 Barney, M.F. & Fisher, W. P., Jr. (2017). Avoiding AI Armageddon with Metrologically-Oriented Psychometrics. 18th International Congress of Metrology. https://doi.org/10.1051/metrology/201709005
- 2016 Barney, M.F. & Fisher, W. P., Jr. (2016). Adaptive Measurement and Assessment. Annual Review of Organizational Psychology and Organizational Behavior, 3, 469-490. https://doi.org/10.1146/annurev-orgpsych-041015-062329
- 2010 Barney, M.F. (2010). Inverted Computer-Adaptive Rasch Measurement: Prospects for Virtual and Actual Reality. IACAT, Arnhem. https://iacat.org/
- Ceiling rule met. Criterion: a judge's ceiling is the highest level it passes before a break, capped at 13; passes above a break do not count, and the level-14 questions are exploratory and never set a ceiling. Unit: one judgment on one offered question. Source: the reasoning-ceiling probe run of 2026-08-19, checked by our internal quality review.