Judge credentialing. Run underway.
Measure the judge before you trust it.
Every judge has a ceiling and its own harshness. AIM measures both, so you can start with the cheapest judge that can do the job.
Every judge has a ceiling.
Each judge gets a ceiling, level by level. Published ceilings come from judges no longer in our roster. The record stays on the Evidence page. Ceiling rule met
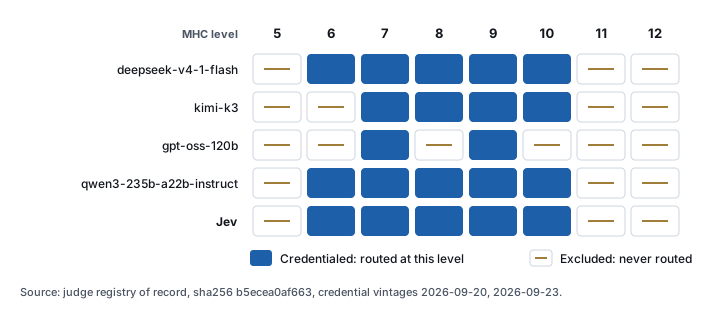
A judge holds a credential only at each level it passed. The grid below shows them. Some were measured twice. The rest are still being credentialed, so they have no ceiling yet.
The bottom of the range is not mapped yet. The board is regenerated after the next judge runs.
Same judges, measured twice.
A judge that drifts moves every score it touched, and nobody notices. So we measured our judges a second time and checked.
We re-measured three LLM judges on the same calibration items in a second paid run: Qwen3 235B Instruct (qwen3-235b-a22b-instruct-2507), DeepSeek V4.1 Flash (deepseek-v4-1-flash) and TypeSafe (Jev).
Test-retest reliability of judge ratings (ICC(2,1), items centered within MHC level): DeepSeek V4.1 Flash 0.993 (95% CI 0.990 to 0.995, 113 items), Qwen3 235B 0.967 (95% CI 0.954 to 0.976, 137 items), TypeSafe 0.999 (95% CI 0.998 to 0.999, 113 items).
Average judge severity drift between the two runs was under 0.01 logit for every judge (DeepSeek +0.005, Qwen3 +0.007, TypeSafe -0.001; standard error about 0.03), statistically equivalent to zero within a pre-declared margin of plus or minus 0.10 logit.
All 19 retested judge-by-level cells (MHC levels 6 to 12) matched their certified calibration within two standard errors, and none showed misfit above the 1.5 mean-square limit.
These judges ran at temperature 0, so much of this stability reflects near-deterministic model output; the figures describe LLM judge stability on a fixed item bank at stage-level grain, not the reliability of scores for people.
DeepSeek V4.1 Flash DeepSeek
0.993
Test-retest ICC(2,1)
95% CI 0.990 to 0.995, 113 items
Qwen3 235B Alibaba
0.967
Test-retest ICC(2,1)
95% CI 0.954 to 0.976, 137 items
Jev TypeSafe
0.999
Test-retest ICC(2,1)
95% CI 0.998 to 0.999, 113 items
Severity drift between the two runs, in logits
DeepSeek V4.1 Flash
+0.005 logit
Qwen3 235B
+0.007 logit
Jev
-0.001 logit
Pre-declared equivalence margin, plus or minus 0.10 logit. Average drift. Line: plus or minus two standard errors.
Four questions to ask your eval judge.
Is the judge measured? How wide is its error bar? Does it fit at each level? Where can it work?
Ask your judge one question.
Is it equally harsh on weak and strong work? Ask that of any judge before you trust its scores. AIM measures each judge before it grades and corrects for its harshness.
In a simulation on judge telemetry from our own runs, harshness left in made a run miss its stated error bar by a wide margin. Corrected, it held. Modeled
Some bias can be fixed. Some must go.
Nine readings of one face. Five are distorted in a consistent way, so each has an exact inverse and can be undone. Three have lost information. No correction brings it back, so they are left out.
Judges work the same way. A judge that leans the same way each time is measured and corrected.
A judge that rates without a pattern at a level is not used there. Nor is one too vague to place the work.
Correcting harshness alone keeps every judge and every question. AIM also checks fit and precision. What fails is dropped.
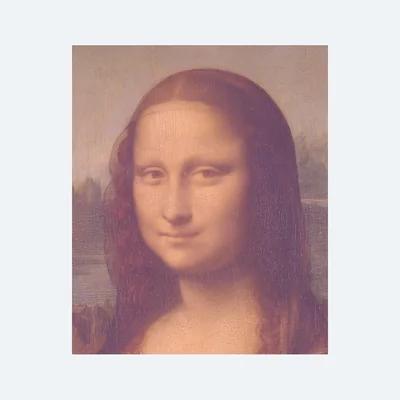
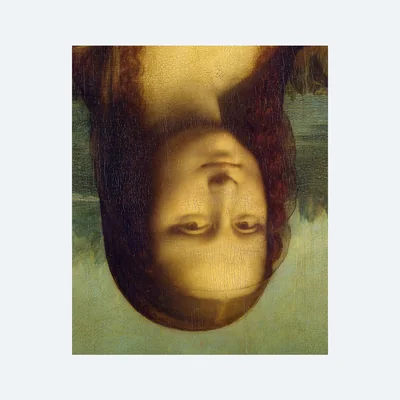
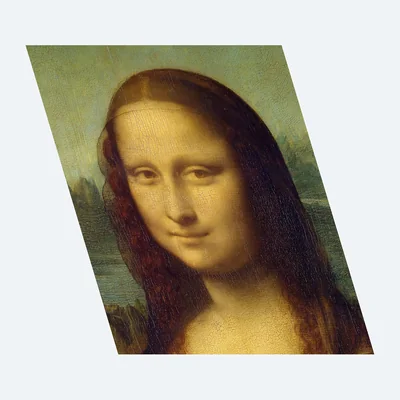
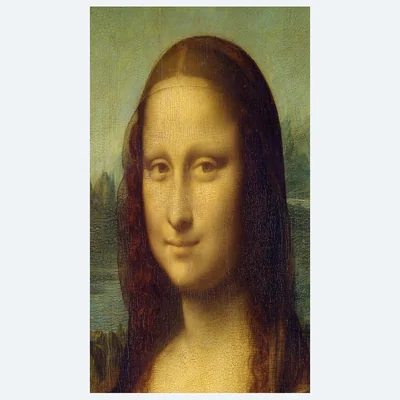
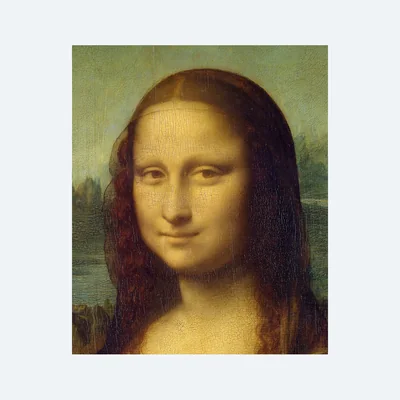
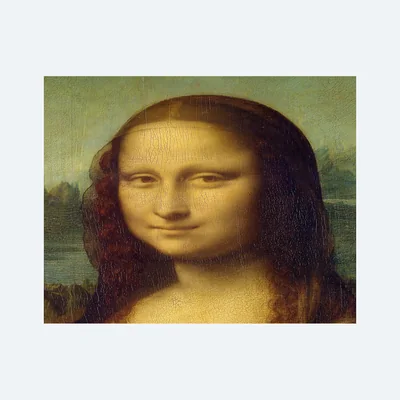
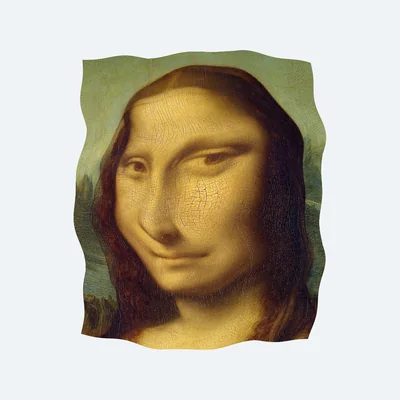
Illustration, an analogy, not data. The numbers below the picture are measured. Correctable distortions have an exact inverse; the others do not. Painting: Leonardo da Vinci, Mona Lisa, public-domain scan (C2RMF) via Wikimedia Commons.
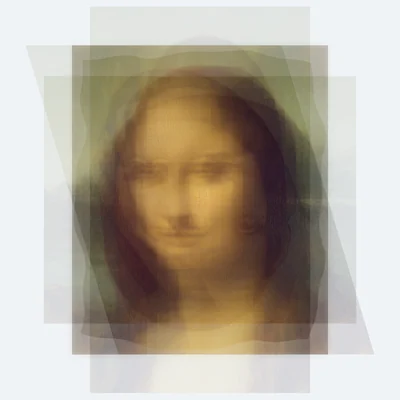
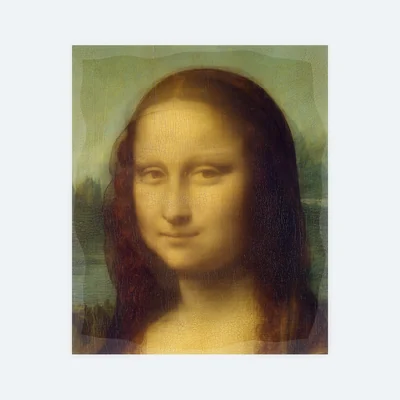
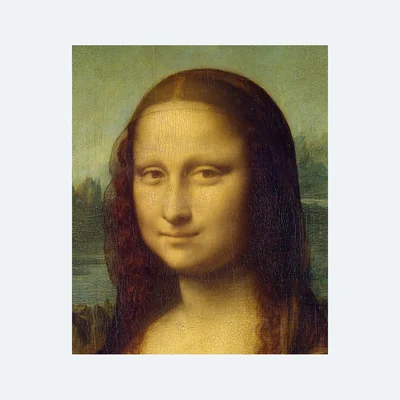
Average all eight readings and every distortion survives, smeared into the result. Pixel error is the mean absolute difference from the true image on a 0 to 255 scale, computed from the tiles above. Analogy, not data.
| Kind of bias | What it looks like | What AIM does |
|---|---|---|
| Uniform harshness or leniency | The judge is consistently harsher or softer | Measures it and removes it |
| Inconsistent rating within a level, or misfit | Ratings do not follow how hard the work is | Does not use the judge at that level |
| An error bar too wide at a level | Too blurred to place the work | Does not use the judge at that level |
| Questions that do not fit the ruler | The question does not behave like the others | Rejects the question at the gate |
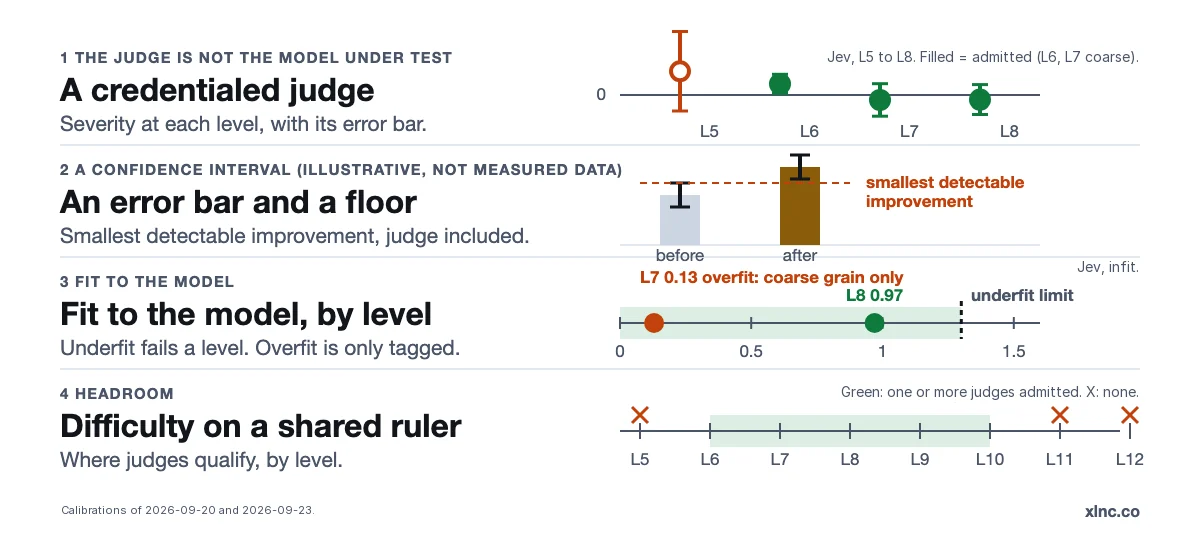
- Corrected, level by level: Jev is harsher at level 6 and more lenient at level 12. One whole-model correction would get one end wrong.
- Excluded: openai-gpt-oss-120b is admitted at levels 7 and 9 only. At levels 6, 8 and 10 it rates inconsistently within the level, and at level 11 its infit is 2.02, above the critical value. It is never routed there.
- Excluded for precision: no judge on this panel is used at levels 11 or 12. Every error bar there is wider than the target. kimi-k3 at level 11 also underfits (infit 1.62).
Judge registry of record b5ecea0af663, credential vintages 2026-09-20 and 2026-09-23.
Escalate only when the error bar stays wide.
The rule: the cheapest judge whose ceiling clears the question takes it. A stronger judge is called only when the error bar crosses a level. Status: ceilings are measured today. Automatic routing is not released.
Hand-off runs on the error bar, not on information gain. The next question is chosen for what it teaches. Each step says why.
The cheapest capable judge starts. A stronger judge waits on stand-by, in build. Stops you set: the widest error bar, the most questions, the most spend.
On a set of 174 located questions, a judge whose ceiling is level 11 leaves 30 above it. No published ceiling clears those 30 today.
In build. Proposed.
Your judge, on the ruler.
Send one model and pick one scale. You get its ceiling, its harshness and a dated report.
Judge calibration is part of the measurement program. The fee is set on a 20-minute scoping call. How buying works
Tell us which judge you are not sure about.
You will get a short note from Matt when a measurement slot opens. Nothing else, no drip sequence.
We store what you send with the few providers our Privacy Policy names, and use it to reply to you. We do not sell it. Email matt@xlnc.co and we delete it. Read our Privacy Policy.
The cheapest capable judge.
Jev is the cheapest capable judge. Under our earlier procedure, Jev holds credentials at levels 6 to 10. Jev is usable at whole-stage grain only, except at level 8. We are re-credentialing Jev under the stricter new procedure. Outside levels 6 to 10, Jev's scores are not counted.
We measure it the same way as the others. It is admitted today, with a condition.
Early evidence; not yet certified.
| Judge | Measured cost per 1,000 ratings | L5 | L6 | L7 | L8 | L9 | L10 | L11 | L12 |
|---|---|---|---|---|---|---|---|---|---|
| Jev | under US$0.01 | not admitted | admitted, whole level only | admitted, whole level only | admitted | admitted, whole level only | admitted, whole level only | not admitted | not admitted |
| openai-gpt-oss-120b | US$0.37 | not admitted | not admitted | admitted, whole level only | not admitted | admitted, whole level only | not admitted | not admitted | not admitted |
| qwen3-235b-a22b-instruct-2507 | US$0.87 | not admitted | admitted | admitted, whole level only | admitted, whole level only | admitted | admitted, whole level only | not admitted | not admitted |
| deepseek-v4-1-flash | US$3.30 | not admitted | admitted, whole level only | admitted, whole level only | admitted, whole level only | admitted, whole level only | admitted | not admitted | not admitted |
| kimi-k3 | US$22.27 | not admitted | not admitted | admitted, whole level only | admitted, whole level only | admitted, whole level only | admitted, whole level only | not admitted | not admitted |
No shared blind spot.
The judges come from many vendors in several countries. The companies that write and attack the new questions do not judge them. No judge scores a question its own company wrote. So no one vendor's blind spot or self-preference decides a score.
The questions are fresh. We write new ones automatically, after the models were trained. We keep them sealed and never publish them. So they could not have been memorized.
Countries are the vendors' home countries.
Judges, levels 7 to 9
In the certified set. GPT-OSS 120B, Qwen3 235B and Jev hold credentials level by level (grid above); Qwen3 235B and Jev were also measured a second time. The others are still being credentialed.
- Gemma 4 31B Google
- Gemma 4 26B Google
- Gemma 3 27B Google
- GPT-6 Luna OpenAI
- GPT-OSS 120B OpenAI
- Mercury 2.5 Inception
- Mistral Small 3.2 Mistral
- Nemotron 3 Nano 30B NVIDIA
- MiMo V2.5 Xiaomi
- Qwen 3 8 Flash Alibaba level 8 only
- Qwen3 235B Alibaba level 8 only
- Jev TypeSafe

Write and attack the questions
- Writes and repairs the questions Anthropic
- Attacks the questions xAI if it passes a reliability check; Anthropic as fallback



Judges, levels 10 to 13
Candidates being screened. Not a final roster.
- A subset of the level 7 to 9 judges levels 10 to 12
- DeepSeek V4.1 Flash DeepSeek credentialed at lower levels (grid above); candidate for levels 10 to 13
- GLM 5.3 Flash Z.ai levels 10 to 12
- Kimi K3 Moonshot level 12 and up
- GPT-6 Astra OpenAI level 13, one-level trial first
Roster as of 2026-10-02. No Anthropic model judges at any level. No xAI model judges at levels 10 to 13. Flags show each vendor's home country.
Vendor and model names are used only to identify the models XLNC measures. XLNC is not affiliated with, sponsored by, or endorsed by these companies, and their inclusion does not imply their approval of any result. All names belong to their respective owners.
- Ceiling rule met. Criterion: a judge's ceiling is the highest level it passes before a break, capped at 13; passes above a break do not count, and the level-14 questions are exploratory and never set a ceiling. Unit: one judgment on one offered question. Source: the reasoning-ceiling probe run of 2026-08-19, checked by our internal quality review.