Published measures
Every published result, with its date.
Each result with its unit, tier and date. Each published ceiling, with its pass counts. Never a bare rank.
The precision we publish.
Simulation
Set to an error bar of 0.20. Delivered at 0.21 once judge harshness is corrected at each level.
Simulation: 15,000 decisions on judge data from our own runs, seed 20260908. With harshness left in, the same run came in at 1.16. Error bars in logits.
Historical record. Gate passed 2026-08-22. Criterion met: a standard error at or below 0.07 of a level for one judge's harshness, with at least 30 judgments, at every level from 8 to 12. Unit: one judgment, with question placements held fixed. Source: a severity calibration run on grok-4-6, 2026-08-20 to 2026-08-22, checked by our internal quality review on 2026-08-22. Question placement error not included.
Historical record. This is the precision of one judge's harshness, grok-4-6, a judge since retired. Its ceiling reading, which set how far up the ruler it was credentialed to grade, is withdrawn pending a re-screen of its successor. The harshness figures are unaffected and hold for the 25 questions and the answer menu used in that run. The error in where those questions sit on the ruler is not included.
Has the ruler moved?
The question set is frozen, fingerprinted and dated. Every run checks the fingerprint first. Whether the ruler holds steady over months is the next exhibit, and it is not done yet.
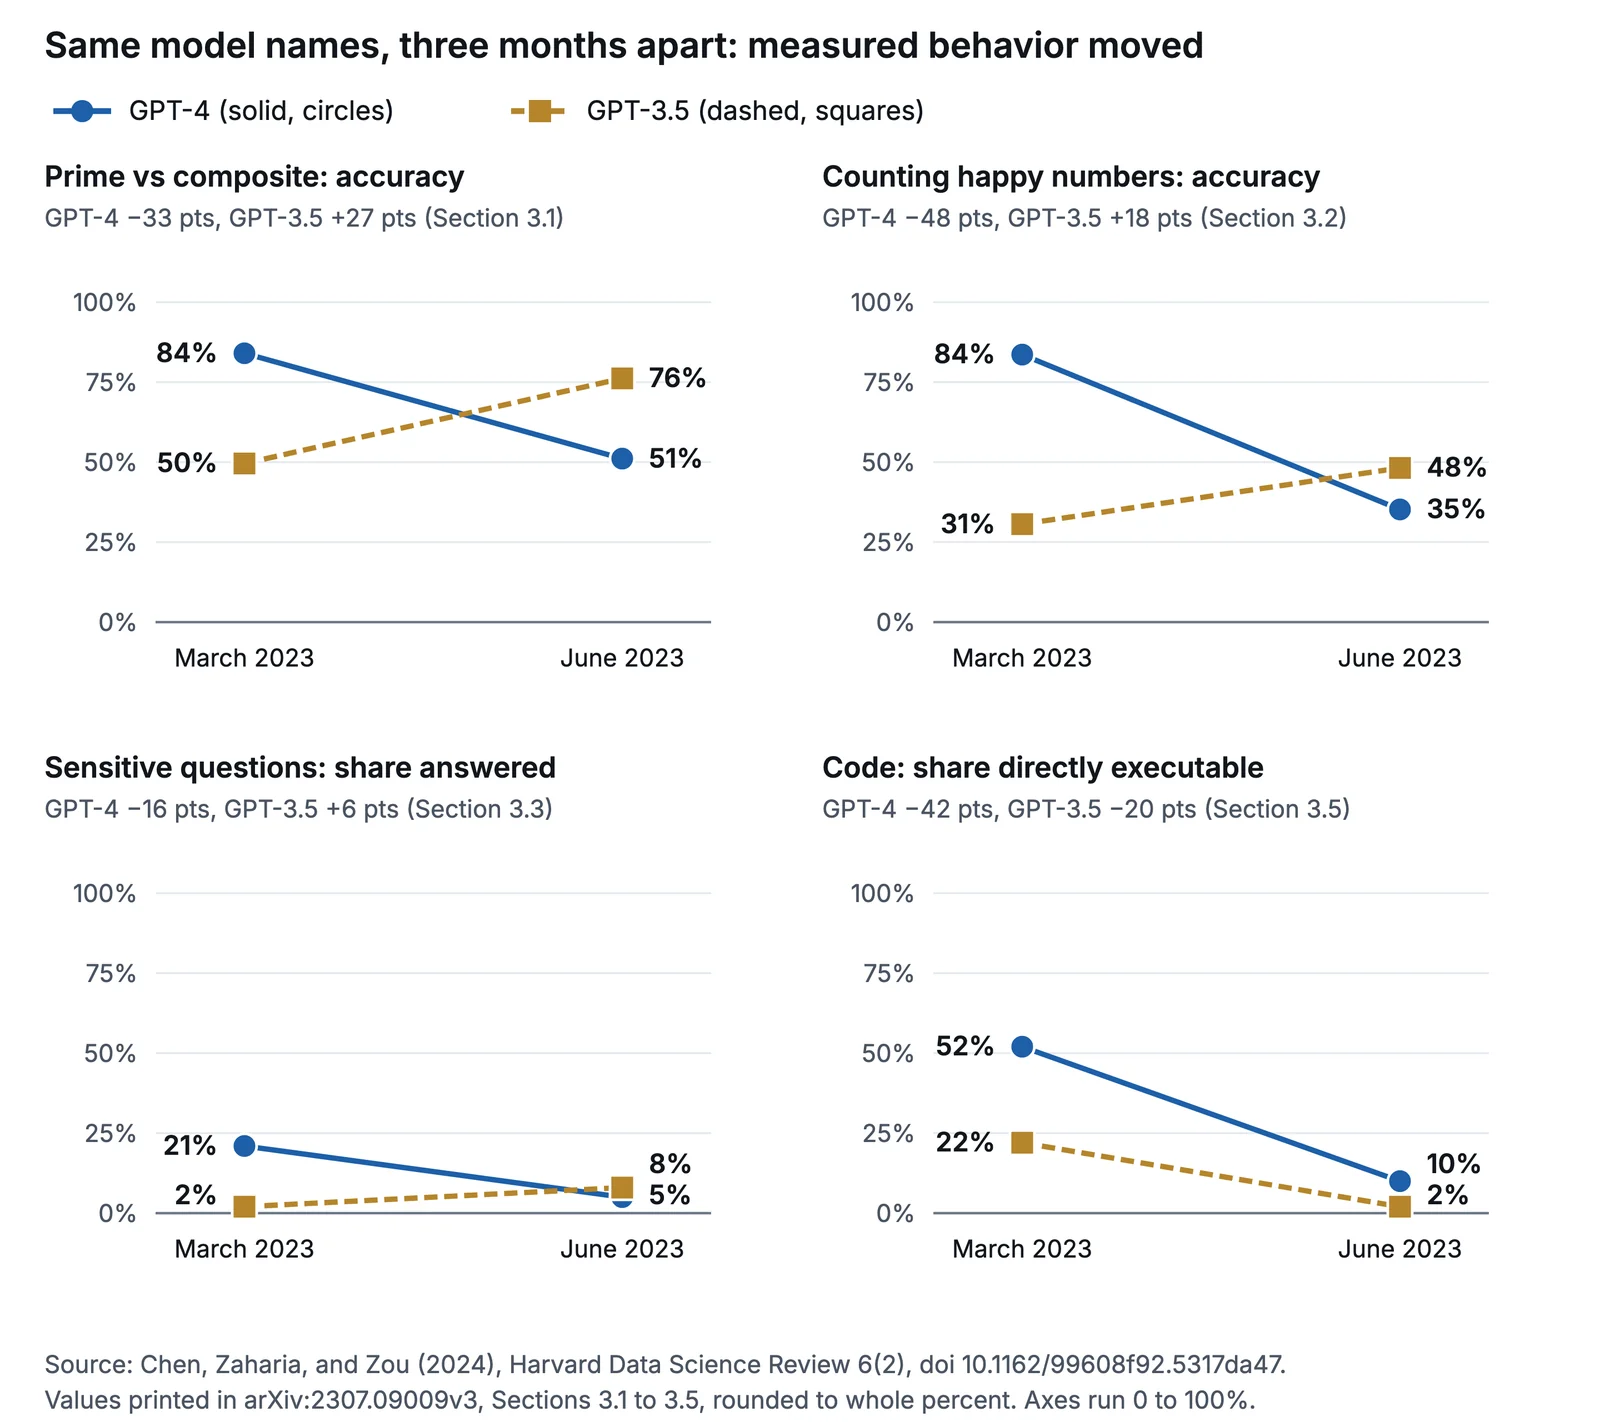
Elsewhere, models have moved. Same model names, three months apart, gave different results.
Our judges, re-measured: shown on the Judges page.
Re-measurement run: published. See the judges' second measurement
Is the ruler circular?
Each level is fixed before any answer is graded. Three more guards keep the ruler from grading itself.
Levels 7 to 9: a certified set of judges, from different vendors and countries, reads the same texts. Each judge is checked against the others. Judge credentialing for levels 7 to 13 is in progress. Each credential is published with its level, standard error and conditions of use.
Levels 10 to 13: the questions are new. One company writes them. A different company attacks them. Neither judges them. The questions stay sealed and unpublished until the judges read them. The judges for these levels are candidates, still being screened.
So the levels are set first. The questions are unseen. And for the new questions, the writer, the attacker and the judges work for separate companies.
A check against outside human experts: still ahead.
Judges, levels 7 to 9
In the certified set. GPT-OSS 120B, Qwen3 235B and Jev hold credentials level by level (grid above); Qwen3 235B and Jev were also measured a second time. The others are still being credentialed.
- Gemma 4 31B Google
- Gemma 4 26B Google
- Gemma 3 27B Google
- GPT-6 Luna OpenAI
- GPT-OSS 120B OpenAI
- Mercury 2.5 Inception
- Mistral Small 3.2 Mistral
- Nemotron 3 Nano 30B NVIDIA
- MiMo V2.5 Xiaomi
- Qwen 3 8 Flash Alibaba level 8 only
- Qwen3 235B Alibaba level 8 only
- Jev TypeSafe

Write and attack the questions
- Writes and repairs the questions Anthropic
- Attacks the questions xAI if it passes a reliability check; Anthropic as fallback



Judges, levels 10 to 13
Candidates being screened. Not a final roster.
- A subset of the level 7 to 9 judges levels 10 to 12
- DeepSeek V4.1 Flash DeepSeek credentialed at lower levels (grid above); candidate for levels 10 to 13
- GLM 5.3 Flash Z.ai levels 10 to 12
- Kimi K3 Moonshot level 12 and up
- GPT-6 Astra OpenAI level 13, one-level trial first
Roster as of 2026-10-02. No Anthropic model judges at any level. No xAI model judges at levels 10 to 13. Flags show each vendor's home country.
Vendor and model names are used only to identify the models XLNC measures. XLNC is not affiliated with, sponsored by, or endorsed by these companies, and their inclusion does not imply their approval of any result. All names belong to their respective owners.
The board.
Published judge ceilings sit at level 11, with a stated condition. Ceiling rule met
Neither of these judges is in the current roster. The record stays here, with its date. The current roster is on the Judges page.
A ceiling is a pass or fail result at each level, so each row shows its pass counts and its date.
The bottom of the range is not mapped yet. The board is regenerated after the next judge runs.
| Judge | Ceiling level | Passes | Condition | Measured | Status |
|---|---|---|---|---|---|
| z-ai-glm-5-3 z.ai | 11 | Break at level 12: 5 of 7. | Passes above the break do not count. | 2026-08-19 | Not in the current judge roster. Record kept. |
| deepseek-v4-flash-0731 DeepSeek | 11 | Break at level 12: 4 of 7. | Passes above the break do not count. | 2026-08-19 | Stale since 2026-09-20: the maker released a new version. Not in the current judge roster. Record kept. |
The grok-4-6 ceiling reading is withdrawn. It waits on a re-screen of the new Grok 4.7 on the corrected ceiling test.
Harsh here, lenient there.
Jev1 sign change beyond the band
openai-gpt-oss-120b1 sign change beyond the band
qwen3-235b-a22b-instruct-2507no sign change beyond the band
deepseek-v4-1-flashno sign change beyond the band
kimi-k3no sign change beyond the band
Above 0 = harsher. Below 0 = more lenient. Pattern only; the exact values stay in the dated report. Shaded band: plus or minus 2 standard errors. Solid dot: admitted at that level; hollow: not admitted. A ring marks a sign change that clears the band on both sides. Level along the bottom. Judge registry of record b5ecea0af663, credential vintages 2026-09-20 and 2026-09-23.
The bend a raw score cannot see.
In a simulation on judge telemetry from our own runs, a run set to a standard error of 0.20 came in at 1.16 with judge harshness left in. With it corrected at each level, 0.21. Error bars are in logits. Modeled1
Simulation.
- Ceiling rule met. Criterion: a judge's ceiling is the highest level it passes before a break, capped at 13; passes above a break do not count, and the level-14 questions are exploratory and never set a ceiling. Unit: one judgment on one offered question. Source: the reasoning-ceiling probe run of 2026-08-19, checked by our internal quality review.
- The simulation used 15,000 simulated certification decisions, seed 20260908, run 2026-09-09, on one judge probe of 2026-09-05. Unit: one simulated draw. Method and results are in the whitepaper. Modeled Whitepaper